ICML 2025
In-Context Deep Learning via Transformer Models
A transformer can train a deep neural network in context without changing its own weights.
Abstract
We investigate whether a transformer can simulate the training of a deep model through in-context learning. We give an explicit construction of a transformer that carries out gradient descent on a multilayer ReLU network while keeping its own weights fixed. The analysis provides approximation and convergence guarantees and extends to softmax-based transformers. Experiments with three-, four-, and six-layer neural networks on synthetic datasets compare in-context training with direct gradient-based training. This establishes a constructive example of learning a deep model entirely through context.
Key results
Learning inside a forward pass
Explicitly construct a transformer that simulates gradient-descent training of a deep ReLU network from information supplied in context.
Provable approximation
Establish approximation and convergence guarantees, including an extension to softmax-based transformers.
Synthetic validation
Compare in-context learning with direct training for deep networks of several depths.
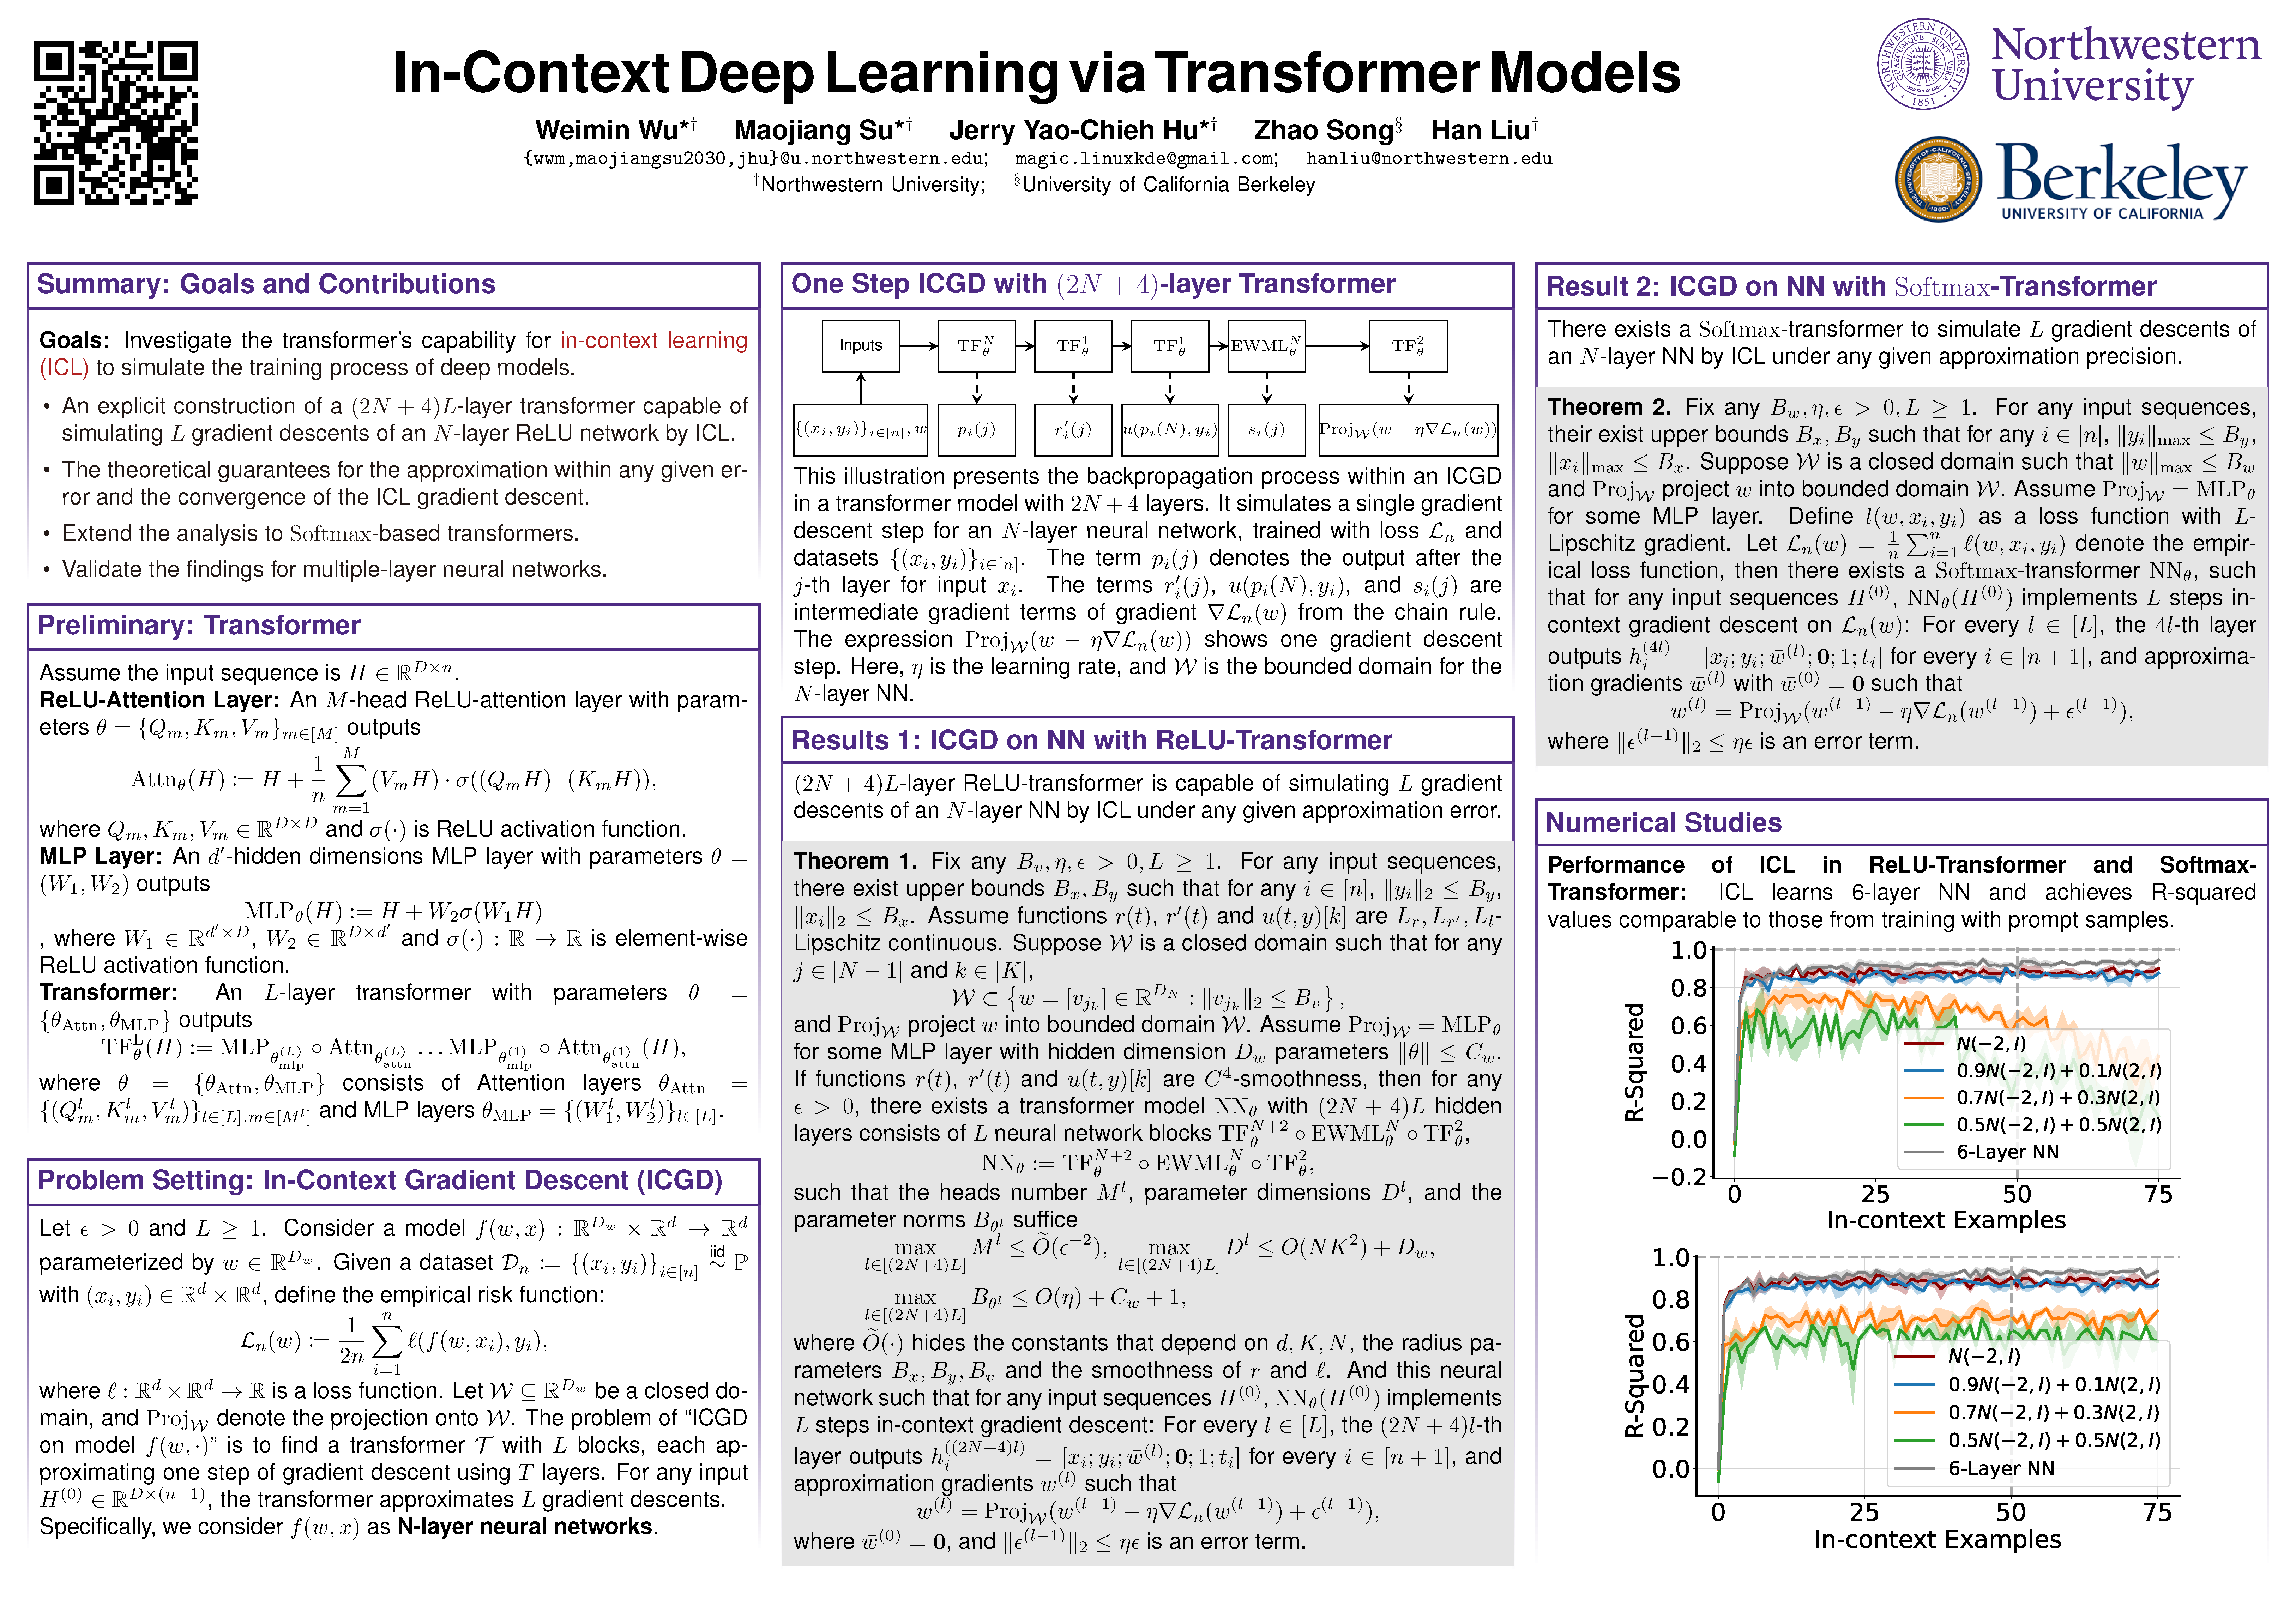
Poster
BibTeX
Official BibTeX from PMLR.
@InProceedings{pmlr-v267-wu25aa,
  title = 	 {In-Context Deep Learning via Transformer Models},
  author =       {Wu, Weimin and Su, Maojiang and Hu, Jerry Yao-Chieh and Song, Zhao and Liu, Han},
  booktitle = 	 {Proceedings of the 42nd International Conference on Machine Learning},
  pages = 	 {67670--67718},
  year = 	 {2025},
  editor = 	 {Singh, Aarti and Fazel, Maryam and Hsu, Daniel and Lacoste-Julien, Simon and Berkenkamp, Felix and Maharaj, Tegan and Wagstaff, Kiri and Zhu, Jerry},
  volume = 	 {267},
  series = 	 {Proceedings of Machine Learning Research},
  month = 	 {13--19 Jul},
  publisher =    {PMLR},
  pdf = 	 {https://raw.githubusercontent.com/mlresearch/v267/main/assets/wu25aa/wu25aa.pdf},
  url = 	 {https://proceedings.mlr.press/v267/wu25aa.html},
  abstract = 	 {We investigate the transformer’s capability for in-context learning (ICL) to simulate the training process of deep models. Our key contribution is providing a positive example of using a transformer to train a deep neural network by gradient descent in an implicit fashion via ICL. Specifically, we provide an explicit construction of a $(2N+4)L$-layer transformer capable of simulating $L$ gradient descent steps of an $N$-layer ReLU network through ICL. We also give the theoretical guarantees for the approximation within any given error and the convergence of the ICL gradient descent. Additionally, we extend our analysis to the more practical setting using Softmax-based transformers. We validate our findings on synthetic datasets for 3-layer, 4-layer, and 6-layer neural networks. The results show that ICL performance matches that of direct training.}
}